
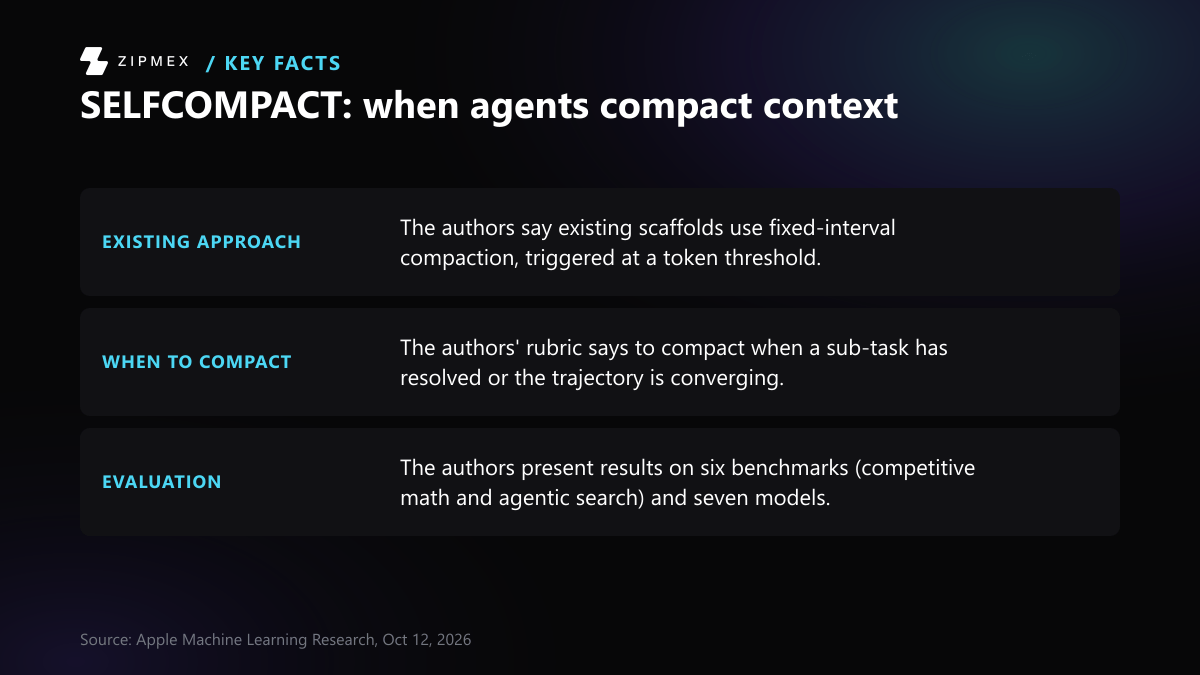
An AI agent can summarize its own working context, but it needs a short rubric telling it when. That is the main finding of "Self-Compacting Language Model Agents," a paper by researchers at Apple and Johns Hopkins University. Apple Machine Learning Research listed it in October 2026, and Apple's page tags it NeurIPS. The method, SelfCompact, gives the model a summarization tool and a checklist. The model compacts when a sub-task has resolved or the work is converging, and holds off mid-derivation or when stuck. The authors report that this matches or beats summarizing at fixed token intervals while costing less. They also report gains of up to 18.1 points on math and 5–9 points on agentic search over no summarization at all. It needs no fine-tuning. Everything here comes from the paper itself. No independent replication has been published.

What the paper is and where it came from
- Authors: Tianjian Li, Jingyu Zhang, William Jurayj, Xi Wang, Chuanyang Jin, Mehrdad Farajtabar, Eric Nalisnick and Daniel Khashabi.
- First posted: arXiv 2606.23525 on 22 June 2026. Version 2 followed on 10 July 2026 (25 pages, cs.CL).
- Latest step: listed on Apple's Machine Learning Research site in October 2026, with a NeurIPS tag.
The problem: context rot in long agent runs
Long agent runs pile up chains of thought and tool-call results. The authors say this stale content steers later steps off course and eventually overflows the context window. Most agent scaffolds deal with this through fixed-interval compaction: once the context passes a token threshold, it gets summarized. The paper's objection is that a threshold ignores what the agent is doing at that moment. It can fire halfway through a derivation or a search and throw away partial results.
How SelfCompact works
SelfCompact has two parts, and the authors say each one fails on its own:
- A compaction tool. The model can call it to summarize its accumulated context. On its own, the open-weight models tested used it unevenly: often at unhelpful moments, or not at all.
- A lightweight rubric. It tells the model when to fire the tool and when to hold back. Without the tool, the rubric has no way to act.
The rubric in practice
The paper's appendix gives two task-specific rubrics.
Math. At each round boundary the model answers three questions:
- Q1 (answer): has the latest round stated a specific final answer?
- Q2 (stuck): did the last two rounds add no new non-trivial fact?
- Q3 (has-next): can the model write the exact next step?
The model compacts if Q1 is yes, or if Q2 and Q3 are both yes. This differs from the abstract's simple "hold off when stuck." In math, being stuck triggers compaction only when the model also has a concrete next step.
Search. The model compacts only when four conditions all hold:
- Its last message is a closed unit, such as a completed tool call.
- It can write 3–5 essential facts with verbatim citations.
- It has made new progress since the last compaction.
- It is not stuck. The paper defines stuck as at least 3 of the last 4 queries returning no new URL or fact.
What the summary keeps
- Math summary: keeps any final answer, key calculations and the reasoning path. It drops false starts and is cut off at 512 tokens.
- Search summary: keeps only facts that are explicitly present in the conversation and can be confirmed. The authors report these summaries run about 1–3k tokens.
Should the agent compact now?
Go through SelfCompact's math rubric at a round boundary to see whether the model should summarize its context or keep working.
Q1 (answer): has the latest round stated a specific final answer?
- Yes → Compact: answer stated
- No → next question
Q2 (stuck): did the last two rounds add no new non-trivial fact?
- Yes, no new fact → next question
- No, new facts were added → Hold: still making progress
Q3 (has-next): can the model write the exact next step?
Q1 is yes, so the rubric fires the compaction tool. The math summary must carry the final answer forward, keep key calculations and the reasoning path, drop false starts, and is cut off at 512 tokens.
Q2 and Q3 are both yes, so the rubric compacts. This is the nuance the abstract's simpler 'hold off when stuck' leaves out: in math, being stuck triggers compaction only when the model also has a concrete next step.
No final answer yet and the last two rounds added new facts, so the rubric holds off. Summarizing here risks cutting into a derivation in progress, which is the paper's objection to fixed token thresholds.
Q2 is yes but Q3 is no, so neither compaction condition is met and the rubric does not fire.
This follows only the paper's math rubric as the authors describe it; it does not cover the separate four-condition search rubric, and the results behind it come from the authors' own tests on open-weight models with no independent replication.
We propose SELFCOMPACT, a scaffold that allows the model itself to decide when and how to compact.
What was tested
| Area | Benchmarks | Models |
|---|---|---|
| Competitive math | IMO-Answerbench, HMMT Nov 2025, HMMT Feb 2026 | Qwen3-4B-Instruct-2507, Qwen3-30B-A3B-Instruct-2507, Qwen3.5-4B, Qwen3.5-9B |
| Agentic search | BrowseComp, BrowseComp-Plus, DeepSearchQA | GLM-4.7-Flash, MiniMax-M2.5, MiMo-V2-Flash |
The baselines were:
- No compaction.
- Fixed-interval summaries: every 16k tokens for math, and at 30% of the context window for search.
- For search only, deleting everything, or keeping the last 3 turns.
- An ablation with the tool but no rubric.
Reported results
- Math: the largest gain over no compaction was 18.1 points, for Qwen3.5-9B on HMMT Feb 2026. The same model gained 16.4 on IMO-Answerbench and 10.0 on HMMT Nov 2025. SelfCompact was best in 11 of 12 math settings. The exception was Qwen3-30B-A3B on HMMT Feb, where fixed-interval summarization won by 1.1 points.
- Search (BrowseComp-Plus): gains of +8.5 (GLM-4.7-Flash), +9.2 (MiniMax-M2.5) and +5.3 (MiMo-V2-Flash). Per-question cost fell by 67%, 63% and 33%.
- Rubric ablation: GLM-4.7-Flash averaged 41.0 without the rubric and 46.4 with it. Qwen3-4B on IMO-Answerbench scored 40.9 without it and 45.5 with it.
Cost is counted as prompt plus completion tokens across all calls, including rubric probes and summarizer calls. It is priced per million tokens and averaged over 150 sampled questions per benchmark. The locally served Qwen math runs are measured as tokens generated rather than in dollars.
The authors call their broader finding a "meta-cognitive gap." Unprompted models cannot reliably tell when their own context has degraded, but a short rubric closes most of that gap without any training.
What it means for people building agents
- Use task-state triggers alongside token thresholds. Rules such as "a sub-task is closed" or "a final answer has been stated" are cheap to check at round boundaries. They avoid summarizing in the middle of a derivation.
- Write explicit rules about what a summary must keep. The rubrics require verbatim facts with citations, and the math summarizer must carry any final answer forward.
- No retraining. Both parts run at inference time, so the method can be tried on existing models.
- Do not assume a model times its own summaries well. The tool-only ablation is where the open-weight models fell short.
Limitations
All results come from the authors' own report on open-weight models only. The authors say frontier models were not tested and training-based methods were out of scope.
